RAG systems for your own documents
Connect your PDFs, contracts, manuals, shared drives and wiki to an AI assistant that answers in plain language and shows the document and page it used. It runs on your own server, offline if needed, or in a German cloud, so your data stays under your control.
Why ChatGPT cannot answer from your files
How a RAG system works
- RRetrieval: find
- The system finds the passages in your sources that fit the question best.
- AAugmented: hand over
- Those passages are added to the question, only from documents the person asking may see.
- GGeneration: answer
- A language model writes the answer from them and names the document and page. If nothing fits, it says so instead of guessing.
Inside: from document to vector database
Start with one use case
Pick one question your team asks every week. Once those answers are right, add the next.
RAG data sources
Hosting and GDPR
- On-premise, offlineA server or workstation in your office, with open-source models running locally. Works without internet.
Best forContracts, health and legal files
- Private cloud in GermanyYour own server in a German data centre, used only by you. No hardware in the office.
Best forTeams in several places
- Hosted AI modelDocuments stay indexed on your system. Only the question and the found passages go to the provider, in an EU region where offered.
Best forThe fastest start
GDPR, point by point
A RAG system reads your documents, and they often hold personal data. These four points cover what the GDPR asks of the setup.
Technical groundwork, not legal advice. Your data protection officer has the final word.
- Art. 28Agreements
- A data processing agreement with every provider that handles personal data.
- Art. 17Deletion
- A document deleted in your system leaves the index at the next sync.
- Art. 5Your logs
- Questions and answers are logged only if you want, on your own system, for as long as you decide.
- Art. 30Documentation
- The data flows written down for your records of processing, and a DPIA where one is needed.
RAG pilot in 4 to 6 weeks
- Free first callWhich questions, from which sources?
- Use case and planOne use case, its sources, and what counts as a good answer.
- PilotYour sources on your setup, tested with your real questions.
- Measured resultHow often the right source was found, on your own test questions.
- Rollout and careMore sources and users, team training, new documents indexed automatically.
Languages and tools
The basics, chosen per project. myRAG below is one combination.
- Languages
- Python
- TypeScript
- Frameworks
- LangChain
- LlamaIndex
- Vector databases
- PostgreSQL with pgvector
- Qdrant
- Embedding models
- bge-m3
- OpenAI embeddings
- Language models
- Ollama (local)
- OpenAI
- Claude
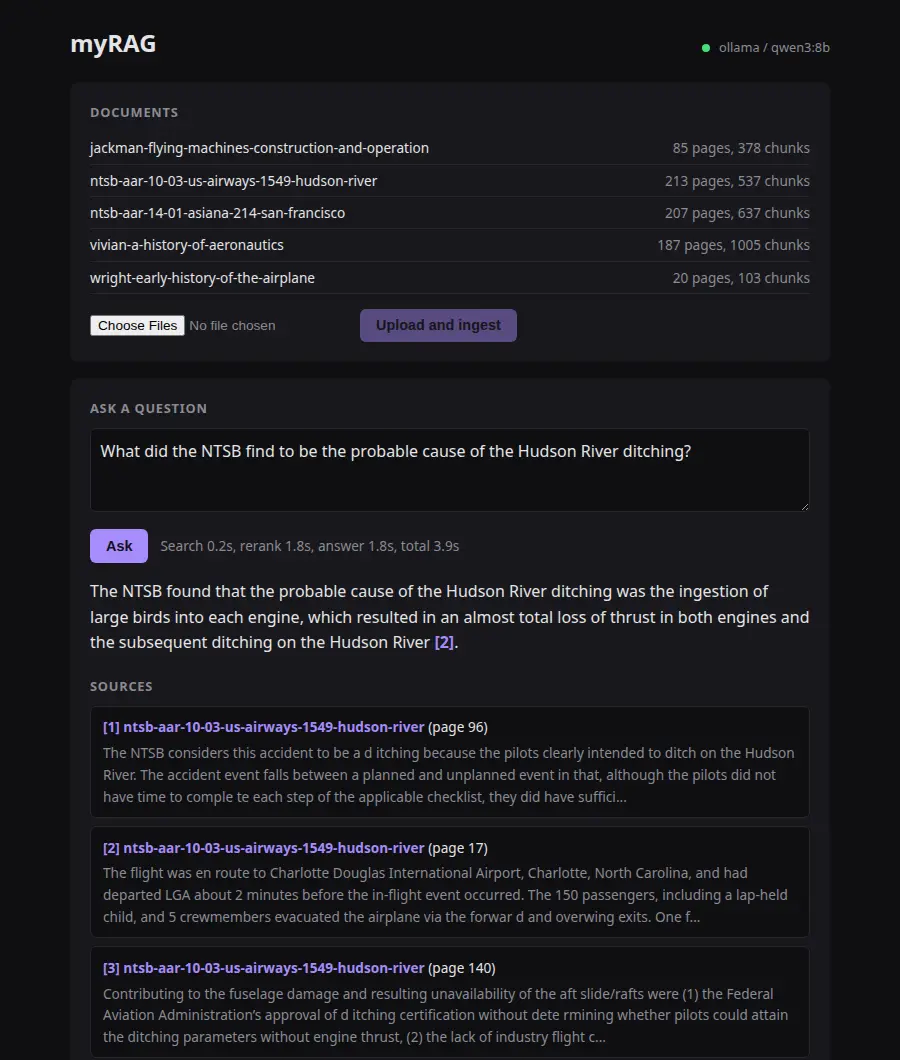
Demo: myRAG
- What it is
- Belambo’s own open-source RAG assistant for PDF documents. A demo, not client work.
- Measured
- The right source in the top five for 85 % of 46 test questions; 98 % of answers true to the source.
- Runs on
- One machine: Python and FastAPI, PostgreSQL with pgvector, bge-m3 embeddings, Qwen3 through Ollama, reranked by the language model.
RAG questions
How is this different from ChatGPT with file uploads?
Uploads cover a few files at a time and leave your company. A RAG system searches all your sources at once, follows your access rights and can run on your own server.
What hardware do I need on-premise?
For a team, usually one workstation or small server with a modern graphics card. You get an exact recommendation in the offer.
Does my data go to ChatGPT?
Only if you choose that. EU-hosted or self-hosted models are the default options, decided per project.
Does Belambo keep any of our data?
No. Belambo stores no user data from your RAG system. Documents, the search index, questions and any logs stay on your server or in your own cloud, for your admins.
Contact
A short message is enough.
Replies within one working day